大家好,今天正式开源发布 HyMT2Sharp(NuGet 包名:Sdcb.HyMT2Sharp.Model,GitHub 仓库:https://github.com/sdcb/HyMT2Sharp )。这是一个纯 C# 实现的腾讯混元翻译大模型 MT2(https://huggingface.co/tencent/Hy-MT2-1.8B )非官方 CPU 推理库:不依赖 llama.cpp,不依赖 ONNX Runtime,自带 AVX2 内核,可面向进程内调用。
仓库语言统计条也是纯紫色的——纯 C#。权重不打进包,自己下载一份 GGUF 就能跑。
它有多快?
大家最关心的肯定是:纯 C# 写的小模型推理,会不会被 llama.cpp 按在地上摩擦?
测试环境是 Ryzen 7 5800X(Zen 3)、Windows、Release、8 线程,avx2=True、vnni=False。不计模型加载与 warmup;prefill 为 512 token 三次平均,decode 为 512 token 上下文后连续生成 128 token。
| 模型 |
prefill 512 |
decode 128 |
prefill 三次 |
| HyMT2Sharp Q1.25 / STQ1_0 |
553.63 tok/s |
43.10 tok/s |
570.5 / 531.1 / 560.8 |
| HyMT2Sharp Q2_0C |
541.00 tok/s |
43.79 tok/s |
560.4 / 506.6 / 559.7 |
| HyMT2Sharp Q4_K_M |
416.33 tok/s |
24.79 tok/s |
417.0 / 412.7 / 419.4 |
| llama.cpp Q4_K_M(build 10894) |
254.93 ± 3.10 tok/s |
27.39 ± 0.37 tok/s |
llama-bench -p 512 -n 128 -t 8 -ngl 0 |
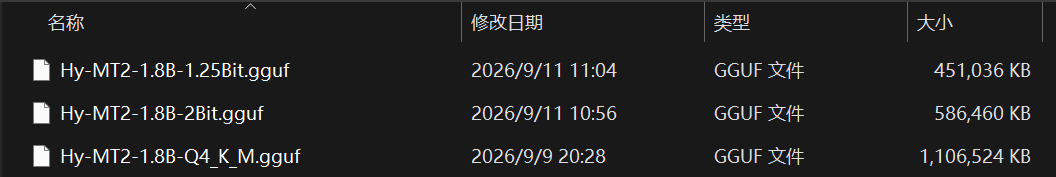
有一点必须先说清楚:Q2_0C 和 1.25-bit STQ1_0 这两种 GGUF,官方 llama.cpp 根本跑不了。 腾讯放出了量化文件,配套的是手机上的加速路径;通用 x86 CPU 上的解码、GEMV/GEMM、panel 重排,是 HyMT2Sharp 重新自研的。Q4_K_M 还能拿 llama.cpp 对一下速度,Q2 / Q1.25 没有这条对照基线——不是我们不愿意比,是上游就没有这条路。
Q4_K_M 上,这份 C# 实现的 prefill 已经比 llama.cpp 快一截。Q1.25 / Q2 的 decode 还能再往上走一档——这两档量化没有 llama.cpp 对照行,因为官方 llama.cpp 不识别 Q2_0C / STQ1_0。表里那行 llama.cpp 只覆盖 Q4_K_M,是此前记录,没有跟本轮绑在一起复测。5800X 连续满载时频率和温度会飘,这些数字不是硬件上限。
换句话说:Q4 比的是"同一条大家都认识的路,C# 能不能更快";Q2 / Q1.25 比的是"这条路官方 CPU 后端根本没铺,我们自己从 GGUF block 布局抠到 AVX2 kernel"。腾讯侧主要给的是硬件加速路径,HyMT2Sharp 的推理后端是重新写的,不是把 llama.cpp 包一层。
当然要泼两盆冷水:
- 目前只支持 x86 CPU 推理(AVX2 路径)。Apple Silicon 那套内置 GPU 已经很强,这个库暂时用不上。
- 测过的量化只有 Q4_K_M、Q2_0C、1.25-bit STQ1_0,其它格式和更大尺寸的 Hy-MT2 没测过。
复现命令:
dotnet run --project src/HyMT2Sharp.Benchmark -c Release -- --model "D:\_\model\Hy-MT2-1.8B-1.25Bit.gguf" --bench-prefill 512 --bench-decode 128 --threads 8
dotnet run --project src/HyMT2Sharp.Benchmark -c Release -- --model "D:\_\model\Hy-MT2-1.8B-Q4_K_M.gguf" --bench-prefill 512 --bench-decode 128 --threads 8
dotnet run --project src/HyMT2Sharp.Benchmark -c Release -- --model "D:\_\model\Hy-MT2-1.8B-2Bit.gguf" --bench-prefill 512 --bench-decode 128 --threads 8
NuGet 包
客户工程一般只装入口包,另外两个会传递引用进来:
dotnet add package Sdcb.HyMT2Sharp.Model
| 包 |
说明 |
Sdcb.HyMT2Sharp.Model |
推理入口:加载 GGUF、分词、KV cache、Forward |
Sdcb.HyMT2Sharp.Gguf |
GGUF v2/v3 读取(通常被 Model 传递引用) |
Sdcb.HyMT2Sharp.Kernels |
AVX2 / AVX-VNNI 量化 kernel(通常被 Model 传递引用) |
HyMT2Sharp.Cli、HyMT2Sharp.Server、HyMT2Sharp.Benchmark 是仓库里的示例和基准工具,不发 NuGet。
GGUF 需要自己下:
CLI 用法
从仓库直接跑(把 --model 换成你的路径):
dotnet run --project src/HyMT2Sharp.Cli -c Release -- --model "D:\_\model\Hy-MT2-1.8B-Q4_K_M.gguf"
不传 --threads 时按 CPU 拓扑自动绑物理 P-core(5800X 上是 8 线程,绑物理核、不占 SMT)。加 --prompt 跑单轮后退出;省略就进入多轮对话。
dotnet run --project src/HyMT2Sharp.Cli -c Release -- --model "D:\_\model\Hy-MT2-1.8B-Q4_K_M.gguf" --prompt "Translate the following segment into Chinese, without additional explanation:SimdPaddleOCR is officially released today (NuGet: Sdcb.SimdPaddleOCR). It is a complete OCR inference engine written entirely in C#. It does not depend on Paddle Inference or ONNX Runtime, and it does not require shipping OpenCV native libraries." --max-tokens 128
网页版用法
HyMT2Sharp.Server 提供 OpenAI 兼容的 POST /v1/chat/completions(含 SSE 流式),并自带聊天页:
dotnet run --project src/HyMT2Sharp.Server -c Release -- --model "D:\_\model\Hy-MT2-1.8B-Q4_K_M.gguf"
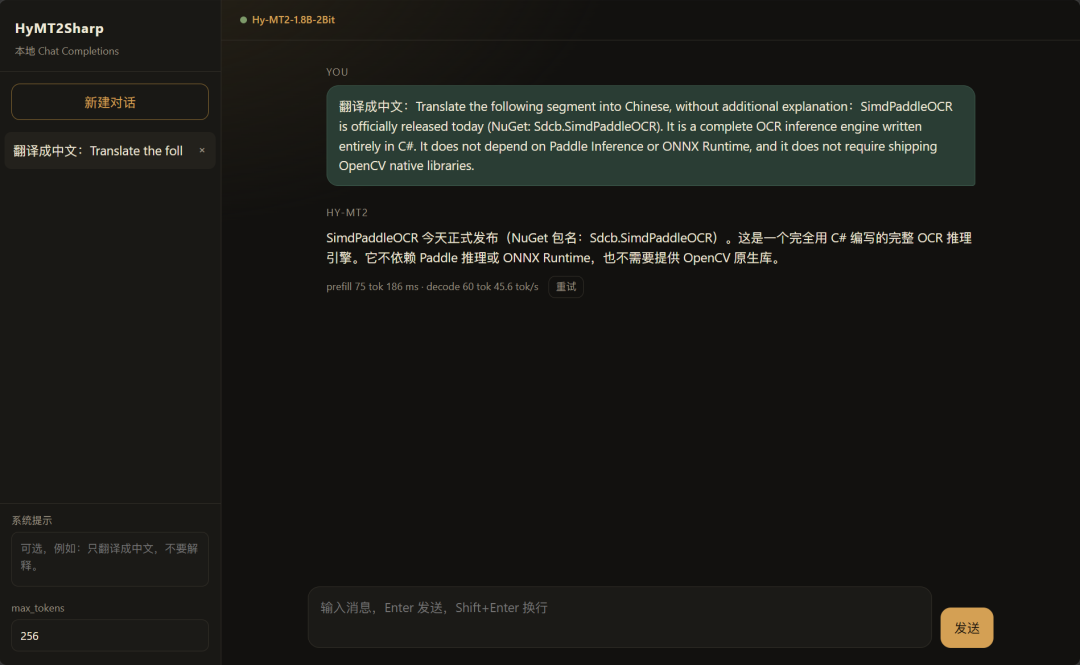
浏览器打开 http://127.0.0.1:8080 。也可以直接 curl:
curl http://127.0.0.1:8080/v1/chat/completions -H "Content-Type: application/json" -d "{\"messages\":[{\"role\":\"user\",\"content\":\"Translate the following segment into Chinese, without additional explanation:SimdPaddleOCR is officially released today (NuGet: Sdcb.SimdPaddleOCR). It is a complete OCR inference engine written entirely in C#. It does not depend on Paddle Inference or ONNX Runtime, and it does not require shipping OpenCV native libraries.\"}],\"max_tokens\":128}"
进程内调用
HunyuanDenseModel 负责加载、分词、KV cache 和 Forward。库里没有内置 Generate / ArgMax,采样和拼接留给调用方。下面是一个最小 greedy 流式示例:
using Sdcb.HyMT2Sharp.Model;

using HunyuanDenseModel model = new(@"D:\_\model\Hy-MT2-1.8B-1.25Bit.gguf");

await foreach (string piece in Generate(model, "Translate the following segment into Chinese, without additional explanation:SimdPaddleOCR is officially released today (NuGet: Sdcb.SimdPaddleOCR). It is a complete OCR inference engine written entirely in C#. It does not depend on Paddle Inference or ONNX Runtime, and it does not require shipping OpenCV native libraries."))
    Console.Write(piece);

static async IAsyncEnumerable<string> Generate(
    HunyuanDenseModel model,
    string user,
    int maxTokens = 128,
    [EnumeratorCancellation] CancellationToken cancellationToken = default)
{
    int[] prompt = model.Tokenizer.Encode(ChatTemplate.RenderHunyuanDense([new ChatMessage("user", user)]));
    float[] logits = model.Forward(model.AlignPrompt(prompt).Suffix);
    await Task.Yield();

    List<int> generated = [];
    string visible = "";
    for (int i = 0; i < maxTokens; i++)
    {
        cancellationToken.ThrowIfCancellationRequested();
        int token = ArgMax(logits);
        if (model.Tokenizer.IsStop(token))
            break;

        generated.Add(token);
        string next = model.Tokenizer.DecodeVisible(generated);
        if (next.Length > visible.Length && next.StartsWith(visible, StringComparison.Ordinal))
            yield return next[visible.Length..];
        visible = next;

        logits = model.Forward([token]);
        await Task.Yield();
    }
}

static int ArgMax(float[] logits)
{
    int best = 0;
    for (int i = 1; i < logits.Length; i++)
        if (logits[i] > logits[best])
            best = i;
    return best;
}
threads = 0(默认)自动绑物理 P-core。实例不是线程安全的,并发请求请排队或各用各的实例。
起源:从 SimdPaddleOCR 到翻译小模型
几天前我写了 SimdPaddleOCR( https://www.cnblogs.com/sdcb/p/22863347/20260907-simdpaddleocr-intro )——用超过 1000 美元的 gpt-5.6-sol 和 Fable 5,做出一个本地高度优化过的纯 C# OCR 推理库。做完之后我有点手痒:有了 System.Runtime.Intrinsics / System.Numerics.Vectors,纯 C# 在 AI 领域还可以干什么?
目光落到了腾讯混元的 Hy-MT2。它最小型号只有 1.8B,足够塞进本机。我对比过 Firefox 的 Bergamot(体积不到 50MB)小模型:Bergamot 很轻,但 Hy-MT2 就算只有 1.8B,它的译文也更自然。说干就干。
差点就没新开项目:TensorSharp
初期其实没准备新开仓库。纯 C# 世界里已经有 TensorSharp( https://github.com/zhongkaifu/TensorSharp ),它也不引用 llama.cpp。Vulkan / CUDA 后端看起来很漂亮,提交记录里还能多次看到 Fable 5.1 的身影——作者显然是认真想把它优化好的。
但我实测下来,它的 CPU 后端没有预想中那么快。当时同一台机器上,托管 CPU 路径比 llama.cpp 慢了 80% 以上:
| 实现 |
pp512 tok/s |
tg128 tok/s |
vs llama.cpp prefill |
vs llama.cpp decode |
| llama.cpp |
356.59 ± 2.65 |
27.47 ± 1.24 |
100% |
100% |
| HyMT2Sharp(本轮) |
163.13 |
19.94 |
46% |
73% |
| HyMT2Sharp(此前 decode 峰值) |
131.55 |
21.82 |
37% |
79% |
TensorSharp --backend cpu(托管) |
45.4 |
13.4 |
13% |
49% |
TensorSharp ggml_cpu |
139.6 |
18.0 |
39% |
66% |
这张表是早期对照,不是今天那台 5800X 上的复测;和上面的 553 tok/s 没有对比关系。它只说明一件事:当时如果只是"拿一个现成的纯 C# 张量库套上去",CPU 上还是会输给 llama.cpp 一大截。
于是这个项目开了。又花了上百美元的普通模型和几十美元的 Fable 5.1 去抠 kernel、panel GEMM、量化路径之后,才有了文首那张表。Q4_K 还能对着 llama.cpp 的现成算子打磨;Q2_0C / STQ1_0 没有现成 CPU 后端可以抄,block 布局、反量化、AVX2 GEMV/GEMM 都是按腾讯放出的 GGUF 自己啃出来的。
一个 C# 写的东西,prefill 可以比 llama.cpp 更快——前提是你接受它现在只做 x86 CPU。这不是"C# 全面超越 llama.cpp",只是在这条被抠过的 Hy-MT2 路径上,托管代码也能把 AVX2 吃饱。Q2 / Q1.25 更进一步:官方通用推理栈走不通,HyMT2Sharp 把这条路铺上了。
开源与交流
仓库:https://github.com/sdcb/HyMT2Sharp 喜欢的话给个 Star。许可证是 Apache-2.0。这个项目从 C#/.Net 技术生态 出发,在没有现成 CPU 后端可抄的情况下,把量化反量化、AVX2 GEMV/GEMM 这些底层算子一点点啃了出来,算是一次挺有意思的开源实战。如果你也在做类似的托管代码推理优化,或者对 大模型本地部署 感兴趣,欢迎去仓库提 issue 或 PR。期待大家的宝贵意见!
 发表于 昨天 23:09
|
查看: 3|
回复: 0


